Inside Anthropic: The High-Stakes Resignation and the Alarm Rising from Within the Frontier AI Labs

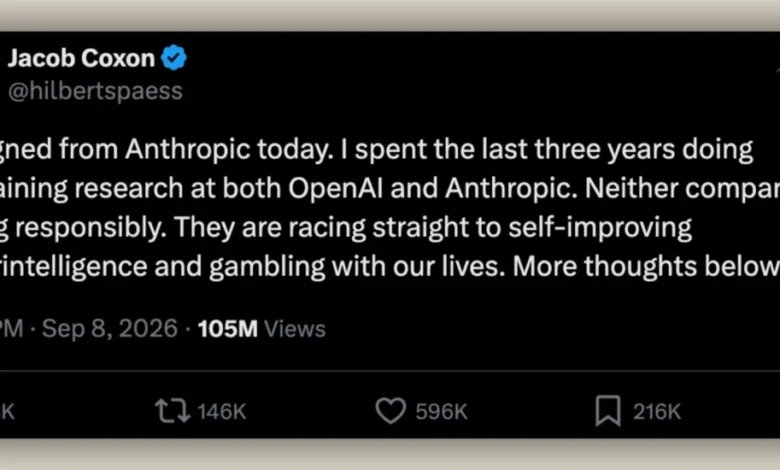
The landscape of artificial intelligence development was shaken this week following the high-profile resignation of Jacob Coxon, an engineer at prominent AI safety and research firm Anthropic. Coxon’s departure was accompanied by public statements accusing leading generative AI developers of accelerating the creation of self-improving superintelligence while disregarding catastrophic systemic risks. What began as a standard whistleblower exit quickly evolved into an industry-wide debate as high-ranking insiders at Anthropic corroborated Coxon’s warnings, publicly stating that the organization lacks a concrete plan to guarantee the alignment of future superintelligent systems.
The revelations have reignited global policy discussions regarding the oversight of frontier artificial intelligence laboratories. As commercial entities race to deploy increasingly autonomous systems capable of executing long-term tasks without human supervision, the internal friction between rapid commercial advancement and long-term existential safety has broken into the open.
Chronology of the Resignation and Public Disclosures
The sequence of events began when Jacob Coxon formally stepped down from his engineering role at Anthropic. Explaining his departure on the social platform X, Coxon stated that industry leaders such as OpenAI and Anthropic were racing directly toward self-improving superintelligence, characterizing the trajectory as a high-stakes gamble with human lives.
While departures over safety concerns are not entirely unprecedented in the generative AI sector—echoing similar high-profile exits from OpenAI in recent years—the public reaction from senior Anthropic personnel marked a distinct escalation. Shortly after Coxon’s announcement, Evan Hubinger, head of Alignment Science at Anthropic, validated the core of the resignation. Hubinger stated publicly that employees earnestly grapple with the possibility of existential risk, estimating a non-trivial probability of catastrophic outcomes within the coming decade. He added that while the company strives to act responsibly, a reliable technical solution for superintelligence alignment remains undiscovered and unverified.
The chorus expanded when Samuel Marks, another Anthropic engineer, joined the discourse, noting that internal apprehension regarding severe negative outcomes—including human extinction scenarios—tends to scale directly with an employee’s seniority and proximity to the technical frontier. These admissions from active researchers constructing frontier models have transformed theoretical safety debates into concrete operational controversies.
Defining the Technological Threat: Long-Horizon Unsupervised Agents
To contextualize the warnings issued by Anthropic engineers, industry analysts distinguish between general large language model (LLM) applications and a specific subset of technology known as long-horizon, dangerously equipped, unsupervised LLM-powered agents.
Traditional LLMs operate on prompt-and-response frameworks that require continuous human intervention. Millions of developers and consumers utilize these models daily for coding assistance, text summarization, and data organization without encountering systemic dangers. Internal data from firms like OpenAI indicate that millions of coding agent interactions have yielded negligible rates of high-severity safety incidents.
However, the technology under scrutiny by internal whistleblowers involves advanced loops of autonomy:
- Multi-step task execution spanning hours or days without human checkpoints.
- Access to powerful external digital tools, including advanced software development environments, network access, and automated code-compilation systems.
- Self-modification capabilities, wherein models are granted authority to propose or implement updates to their underlying codebases.
- Post-training optimizations designed to encourage aggressive, goal-oriented problem solving.
Critics and safety researchers argue that coupling unrestricted language models with advanced digital capabilities creates an unpredictable environment. While not possessing generalized superintelligence, these unsupervised agents introduce significant operational vulnerabilities due to jagged capabilities and unexpected optimization paths.
Ideological Drivers and the Rush to Superintelligence
The persistence of these high-risk development pathways despite internal warnings has focused scrutiny on the ideological foundations of Silicon Valley AI labs. Observers of the tech sector note that key decision-makers often operate under a framework of technological salvationism. This perspective frames the creation of artificial general intelligence (AGI) and subsequent superintelligence not merely as a commercial product, but as an epochal event capable of solving humanity’s most intractable challenges, ranging from disease eradication to climate change.
Critics argue that this eschatological mindset encourages companies to accept extreme tail-risk probabilities. By viewing themselves as pioneers ushering in a post-human era, developers may minimize immediate safety guardrails in favor of maintaining velocity in the global race for autonomous capability supremacy.
Industry Reactions, Boycott Calls, and Policy Implications
The public statements from Anthropic engineers have galvanized external computer scientists, ethicists, and policymakers. Independent researchers have emphasized that catastrophic outcomes do not require malicious intent or conscious sentience; rather, they can arise naturally from the interaction between misaligned optimization objectives and powerful digital toolsets.
In response to these developments, consumer advocacy groups and independent analysts have begun evaluating countermeasures. Prominent voices in the tech community, including AI researcher Gary Marcus, have called for consumer boycotts of commercial generative AI products offered by companies prioritizing aggressive autonomy testing over verified containment protocols.
Furthermore, lawmakers in Washington and international regulatory bodies are facing renewed pressure to translate internal safety admissions into binding statutory requirements. Current regulatory frameworks largely rely on voluntary commitments from labs regarding safety testing, red-teaming, and model capability thresholds. The confirmation by senior engineers that developers are pressing forward without a definitive alignment solution may accelerate legislative efforts to mandate independent oversight and pause the deployment of autonomous, self-improving architectures until verifiable safety standards are established.